CaYaScribe
Published:
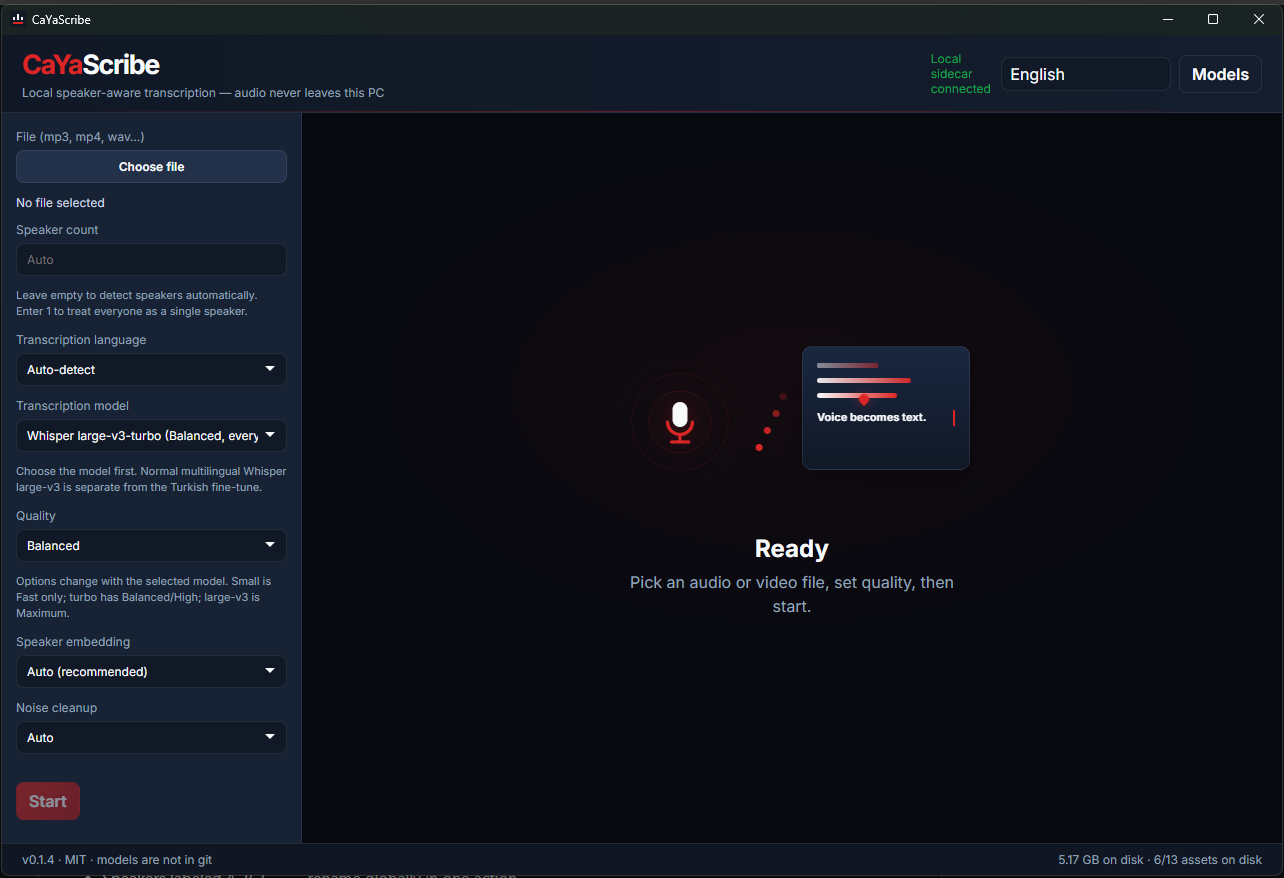
Local, offline speaker-aware transcription for Windows. Audio and video never leave your machine.
CaYaScribe Local, offline speaker-aware transcription for Windows. Audio and video never leave your machine. Languages: English (default) · Türkçe The app UI is English or Turkish. The OS/browser language is used on first launch; anything other than Turkish falls back to English. You can switch in the title bar. Transcription itself covers 99+ languages (Whisper); an unknown language code is treated as English. What it does Extracts audio from MP3, MP4 and other media (LGPL FFmpeg) Transcribes in 99+ languages (Whisper; Turkish and English are first-class) Optional speaker diarization: empty count = auto-detect, 1 = single speaker Speakers labeled A, B, C… — rename globally in one action Export TXT / SRT / VTT / JSON; timestamps are optional On first launch, asks before downloading missing models; you can also download later from Models Releases Windows installers are published on GitHub Releases. Push a tag vX.Y.Z to build NSIS (.exe) and attach it to the release Models are not inside the installer; the app downloads them after you consent The installer includes the local Python engine; models download after you consent See docs/releasing.md. Development setup Requires: Windows 10+, Python 3.12+, Node 20+, Rust (Tauri). On first run the app offers FFmpeg, Whisper turbo, the Turkish Whisper large-v3 fine-tune, pyannote segmentation, and WeSpeaker ResNet293-LM. Uncheck what you do not need. Quality profiles Profile Engine (v0.1) Fast Whisper small Balanced (default) Whisper large-v3-turbo High Turkish Whisper large-v3 fine-tune when downloaded; else turbo Maximum Same TR fine-tune, else multilingual large-v3 Speaker diarization is language-independent (sherpa-onnx + TitaNet). No Hugging Face token is required for the default path. Privacy Speech-to-text never goes to the cloud Downloads happen only after you confirm, from Hugging Face / GitHub No telemetry Architecture: docs/design.md License App code: MIT. Third-party: THIRDPARTYNOTICES.md
Özellikler
- Extracts audio from MP3, MP4 and other media (LGPL FFmpeg)
- Transcribes in 99+ languages (Whisper; Turkish and English are first-class)
- Optional speaker diarization: empty count = auto-detect, 1 = single speaker
- Speakers labeled A, B, C… — rename globally in one action
- Export TXT / SRT / VTT / JSON; timestamps are optional
- On first launch, asks before downloading missing models; you can also download later from Models
- Push a tag vX.Y.Z to build NSIS (.exe) and attach it to the release
- Models are not inside the installer; the app downloads them after you consent
- The installer includes the local Python engine; models download after you consent
- Speech-to-text never goes to the cloud
- Downloads happen only after you confirm, from Hugging Face / GitHub
- No telemetry